
Mixed-Integer Quadratic Programming (MIQP)#
A tutorial for first-year PhD students on formulating and solving mixed-integer quadratic programs.
Learning Objectives#
By the end of this notebook you will be able to:
Explain how MIQP extends QP with integrality constraints
Formulate cardinality-constrained portfolio optimization as an MIQP
Model facility location problems with quadratic shipping costs
Understand how QP relaxations are solved at each node of the Branch-and-Bound tree
Analyze the trade-off between discrete decisions and quadratic objectives
Prerequisites: Basic optimization, familiarity with Python and NumPy. The LP, QP, and MILP tutorials in this series are helpful but not required.
References: This tutorial draws on the portfolio optimization framework of [Markowitz, 1952] and the integer programming foundations of [Wolsey, 1998].
import discopt.modeling as dm
import numpy as np
1. What is MIQP?#
A Quadratic Program (QP) minimizes a quadratic objective subject to linear constraints:
where \(Q \succeq 0\) (positive semidefinite) ensures convexity. QPs arise naturally in portfolio optimization, control, and regression.
A Mixed-Integer Quadratic Program (MIQP) adds integrality constraints on some variables:
This combines the richness of quadratic objectives (modeling risk, nonlinear costs, interactions) with the combinatorial power of discrete decisions (select/reject, open/close, on/off).
How discopt solves MIQPs#
discopt automatically detects MIQP structure via its problem classifier. The solver then uses Branch and Bound [Wolsey, 1998], where at each node of the search tree the integrality constraints are relaxed to produce a QP subproblem. These QP relaxations are solved efficiently by a specialized interior-point method (IPM) implemented in JAX [Nocedal and Wright, 2006]. The Rust backend manages the B&B tree, branching decisions, and pruning.
Bulk API for large-scale MIQPs: When \(Q\) and \(A\) are available as NumPy arrays,
Model.add_quadratic_objective(Q, c, x)andModel.add_linear_constraints(A, b, x)accept matrix/vector data directly, avoiding per-element Python loops. This is significantly faster for problems with hundreds of variables or more.
Common applications#
Application |
Quadratic term |
Integer variables |
|---|---|---|
Portfolio optimization |
Risk (variance) |
Asset selection (cardinality) |
Facility location |
Quadratic shipping costs |
Open/close decisions |
Lot sizing |
Quadratic holding costs |
Setup decisions |
Sensor placement |
Quadratic coverage model |
Sensor on/off |
Regression with feature selection |
Squared error |
Feature inclusion |
2. Example 1: Cardinality-Constrained Portfolio Optimization#
The Markowitz mean-variance framework [Markowitz, 1952] selects portfolio weights \(w\) to minimize variance for a given target return:
In practice, fund managers often want to limit the number of assets held (to reduce transaction costs, monitoring burden, etc.). This cardinality constraint requires binary indicator variables \(z_i \in \{0, 1\}\), turning the problem into an MIQP:
subject to:
\(\mu^\top w \geq r_{\text{target}}\) (return target)
\(\mathbf{1}^\top w = 1\) (fully invested)
\(\sum_i z_i \leq K\) (at most \(K\) assets)
\(0.02 \cdot z_i \leq w_i \leq 0.40 \cdot z_i\) (position bounds linked to selection)
\(z_i \in \{0, 1\}\)
The linking constraints \(w_i \leq 0.40 \cdot z_i\) ensure that if asset \(i\) is not selected (\(z_i = 0\)), its weight is zero. The lower bound \(w_i \geq 0.02 \cdot z_i\) prevents tiny, impractical positions.
# --- Asset data: 8 assets ---
n_assets = 8
np.random.seed(42)

# Expected returns
mu = np.array([0.12, 0.10, 0.07, 0.03, 0.15, 0.08, 0.11, 0.06])

# Covariance matrix via lower-triangular factor
L = np.diag([0.10, 0.08, 0.06, 0.04, 0.12, 0.07, 0.09, 0.05])
L[1, 0] = 0.02
L[2, 0] = 0.01
L[3, 1] = 0.01
L[4, 0] = 0.03
L[5, 2] = 0.01
L[6, 1] = 0.02
L[7, 3] = 0.01
Sigma = L @ L.T

# Target return
r_target = 0.09

print("Expected returns:", mu)
print("\nCovariance matrix (8x8):")
print(np.array2string(Sigma, precision=4, suppress_small=True))
print(f"\nTarget return: {r_target}")
Expected returns: [0.12 0.1  0.07 0.03 0.15 0.08 0.11 0.06]

Covariance matrix (8x8):
[[0.01   0.002  0.001  0.     0.003  0.     0.     0.    ]
 [0.002  0.0068 0.0002 0.0008 0.0006 0.     0.0016 0.    ]
 [0.001  0.0002 0.0037 0.     0.0003 0.0006 0.     0.    ]
 [0.     0.0008 0.     0.0017 0.     0.     0.0002 0.0004]
 [0.003  0.0006 0.0003 0.     0.0153 0.     0.     0.    ]
 [0.     0.     0.0006 0.     0.     0.005  0.     0.    ]
 [0.     0.0016 0.     0.0002 0.     0.     0.0085 0.    ]
 [0.     0.     0.     0.0004 0.     0.     0.     0.0026]]

Target return: 0.09
def build_portfolio(K, n_assets=8, mu=mu, Sigma=Sigma, r_target=0.09):
    """Build a cardinality-constrained portfolio MIQP."""
    m = dm.Model(f"portfolio_K{K}")

    # Binary selection variables
    z = m.binary("z", shape=(n_assets,))

    # Continuous weight variables (linked to selection)
    w = m.continuous("w", shape=(n_assets,), lb=0.0, ub=0.4)

    # Minimize portfolio variance: w' * Sigma * w
    # Expand the quadratic form explicitly
    variance = dm.sum(
        lambda i: dm.sum(lambda j: Sigma[i, j] * w[i] * w[j], over=range(n_assets)),
        over=range(n_assets),
    )
    m.minimize(variance)

    # Fully invested
    m.subject_to(dm.sum(lambda i: w[i], over=range(n_assets)) == 1.0, name="budget")

    # Return target
    m.subject_to(
        dm.sum(lambda i: mu[i] * w[i], over=range(n_assets)) >= r_target, name="return_target"
    )

    # Cardinality constraint
    m.subject_to(dm.sum(lambda i: z[i], over=range(n_assets)) <= K, name="cardinality")

    # Linking constraints: w[i] active only if z[i] = 1
    for i in range(n_assets):
        m.subject_to(w[i] <= 0.4 * z[i], name=f"upper_link_{i}")
        m.subject_to(w[i] >= 0.02 * z[i], name=f"lower_link_{i}")

    return m, w, z


# Build and inspect for K=4
m_demo, _, _ = build_portfolio(K=4)
print(m_demo.summary())
Model: portfolio_K4
  Variables: 16 (8 continuous, 8 integer/binary)
  Constraints: 19
  Objective: minimize Σ[8 terms]
  Parameters: 0
# Verify discopt detects this as MIQP
from discopt._relax.problem_classifier import ProblemClass, classify_problem

pclass = classify_problem(m_demo)
print(f"Problem class: {pclass}")
assert pclass == ProblemClass.MIQP, f"Expected MIQP, got {pclass}"
Problem class: ProblemClass.MIQP
Note
The cell below prints OA: nonlinear objective is not convex in the optimization sense; disabling master lower-bound updates and skipping objective OA cuts. The
objective is convex; the outer-approximation route’s own convexity classifier
false-negatives on a quadratic written as a nested dm.sum
(#1352). It costs bound quality,
not soundness — declaring the objective non-convex makes OA decline to update its
master lower bound, which is the conservative direction — so the answer below is
correct and certified. The line is left in rather than filtered, so the cost stays on
the record. qp_solver works through it in full.
# Sweep K = 3, 4, 5, 6, 7, 8 and collect results
K_values = [3, 4, 5, 6, 7, 8]
results = []

for K in K_values:
    m_k, w_k, z_k = build_portfolio(K)
    res = m_k.solve()
    z_vals = res.value(z_k)
    selected = [i for i in range(n_assets) if z_vals[i] > 0.5]
    results.append(
        {
            "K": K,
            "risk": res.objective,
            "selected": selected,
            "nodes": res.node_count,
            "time": res.wall_time,
        }
    )

# Display results table
print(f"{'K':>3}  {'Risk (var)':>12}  {'Nodes':>6}  {'Time (s)':>9}  Selected Assets")
print("-" * 70)
for r in results:
    print(f"{r['K']:3d}  {r['risk']:12.6f}  {r['nodes']:6d}  {r['time']:9.3f}  {r['selected']}")
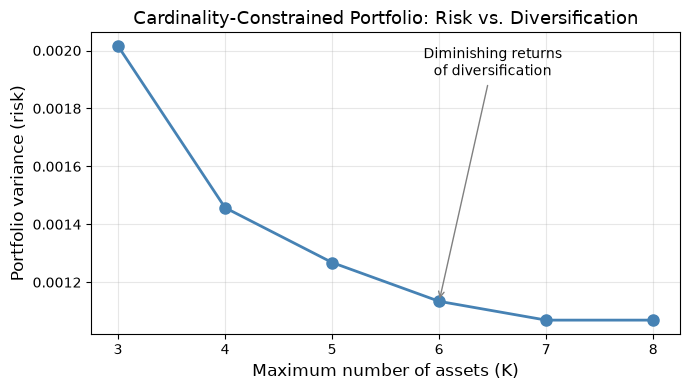
  K    Risk (var)   Nodes   Time (s)  Selected Assets
----------------------------------------------------------------------
  3      0.002015      63      0.124  [4, 5, 7]
  4      0.001457      81      0.078  [4, 5, 6, 7]
  5      0.001268      73      0.061  [0, 4, 5, 6, 7]
  6      0.001134      13      0.038  [1, 2, 4, 5, 6, 7]
  7      0.001069       3      0.030  [0, 1, 2, 4, 5, 6, 7]
  8      0.001069       3      0.029  [0, 1, 2, 4, 5, 6, 7]
About the
OA: nonlinear objective is not convex ...warning above. The Markowitz objective \(w^\top \Sigma w\) is convex here — \(\Sigma = LL^\top\) is positive semi-definite by construction, and you can check its eigenvalues are all positive. The warning comes from a conservative classification, not from a wrong one: the objective is written as an expanded sum of bilinear products \(\sum_i \sum_j \Sigma_{ij} w_i w_j\), and the rule-based curvature classifier that the outer-approximation path consults works structurally on the expression DAG. It cannot establish that such a sum is convex without an eigenvalue argument, so it reports “not convex”.The consequence is a weaker bound, never a wrong one: OA responds by disabling master lower-bound updates and skipping objective cuts, which is the safe direction. The optimal values reported above are unaffected — they match an independent solve of the same models.
discopt does have a numerical convexity certificate that proves this objective convex, but the OA path does not request it by default. That is tracked in issue #1352 — and the issue is deliberately not just “turn the certificate on”: forcing it on this model makes the OA path stop at the root with a slightly suboptimal incumbent and certify it, so the conservative classification is currently masking a second defect. Until that is root-caused, the conservative behaviour you see here is the one you want.
import matplotlib.pyplot as plt

fig, ax = plt.subplots(1, 1, figsize=(7, 4))

Ks = [r["K"] for r in results]
risks = [r["risk"] for r in results]

ax.plot(Ks, risks, "o-", color="steelblue", linewidth=2, markersize=8)
ax.set_xlabel("Maximum number of assets (K)", fontsize=12)
ax.set_ylabel("Portfolio variance (risk)", fontsize=12)
ax.set_title("Cardinality-Constrained Portfolio: Risk vs. Diversification", fontsize=13)
ax.set_xticks(Ks)
ax.grid(True, alpha=0.3)

# Annotate the diminishing returns
ax.annotate(
    "Diminishing returns\nof diversification",
    xy=(6, risks[3]),
    xytext=(6.5, risks[0] * 0.95),
    fontsize=10,
    ha="center",
    arrowprops=dict(arrowstyle="->", color="gray"),
)

plt.tight_layout()
plt.show()
Interpretation#
The plot reveals a key insight: diversification has diminishing returns. Going from \(K=3\) to \(K=4\) assets substantially reduces risk, but going from \(K=7\) to \(K=8\) yields almost no improvement. In practice, this means a fund manager can achieve near-optimal risk reduction with a modest number of assets, avoiding the monitoring and transaction costs of a large portfolio.
Notice also that the B&B node count varies with \(K\). When \(K\) is very small or very large, the problem is relatively easy (few feasible combinations, or the cardinality constraint is slack). Intermediate values of \(K\) tend to be the hardest, as the solver must explore more of the search tree.
3. Example 2: Warehouse Selection with Congestion Costs#
A logistics company must choose which of 6 candidate warehouses to open in order to serve 10 customers. Shipping cost per unit of flow grows with the square of the distance (fuel consumption, perishable-goods degradation), and each lane additionally suffers congestion: the cost of a lane grows with the square of the volume routed over it.
subject to:
\(\sum_i \text{alloc}_{ij} = 1 \quad \forall j\) (each customer fully served)
\(\text{alloc}_{ij} \leq \text{open}_i \quad \forall i, j\) (only open warehouses can serve)
\(\sum_j \text{alloc}_{ij} \leq C_i \cdot \text{open}_i \quad \forall i\) (warehouse capacity)
\(\sum_i \text{open}_i \leq 3\) (budget: at most 3 warehouses)
\(\text{open}_i \in \{0, 1\}\), \(\text{alloc}_{ij} \in [0, 1]\)
Which term actually makes this an MIQP? Only the last one. It is tempting to read \(d_{ij}^2 \cdot \text{alloc}_{ij}\) as “the quadratic term”, but \(d_{ij}\) is data: squaring it produces a number, and the term stays linear in the decision variable \(\text{alloc}_{ij}\). A model whose objective is \(\sum d_{ij}^2 \, \text{alloc}_{ij}\) with linear constraints classifies as an MILP, however nonlinear the coefficients look. What raises the problem class is a product of decision variables — here \(\text{alloc}_{ij}^2\), the congestion term.
This distinction is worth internalizing: problem class is a property of the expression DAG in the variables, not of how the numbers were computed.
The congestion term is convex (\(\gamma > 0\)), so every node relaxation is a convex QP. It also has an economic consequence you can see in the output: because the cost of a lane is convex in its volume, it is cheaper to split a customer’s demand across several open warehouses than to route all of it down one lane.
# Warehouse and customer locations (2D coordinates)
np.random.seed(7)
n_warehouses = 6
n_customers = 10

warehouse_pos = np.array(
    [
        [1.0, 8.0],
        [3.0, 2.0],
        [7.0, 9.0],
        [9.0, 3.0],
        [5.0, 5.0],
        [2.0, 6.0],
    ]
)
customer_pos = np.array(
    [
        [2.0, 7.0],
        [4.0, 3.0],
        [6.0, 8.0],
        [8.0, 2.0],
        [1.0, 4.0],
        [5.0, 6.0],
        [3.0, 9.0],
        [7.0, 1.0],
        [9.0, 7.0],
        [4.0, 5.0],
    ]
)

# Squared Euclidean distances
dist_sq = np.zeros((n_warehouses, n_customers))
for i in range(n_warehouses):
    for j in range(n_customers):
        diff = warehouse_pos[i] - customer_pos[j]
        dist_sq[i, j] = np.dot(diff, diff)

# Fixed costs and capacities
fixed_costs = np.array([50.0, 60.0, 45.0, 55.0, 70.0, 40.0])
capacities = np.array([4.0, 3.0, 4.0, 3.0, 5.0, 3.0])  # max customers served

print("Warehouse positions:")
for i in range(n_warehouses):
    print(
        f"  W{i}: ({warehouse_pos[i, 0]:.0f}, {warehouse_pos[i, 1]:.0f})  "
        f"cost={fixed_costs[i]:.0f}, cap={capacities[i]:.0f}"
    )
print("\nCustomer positions:")
for j in range(n_customers):
    print(f"  C{j}: ({customer_pos[j, 0]:.0f}, {customer_pos[j, 1]:.0f})")
Warehouse positions:
  W0: (1, 8)  cost=50, cap=4
  W1: (3, 2)  cost=60, cap=3
  W2: (7, 9)  cost=45, cap=4
  W3: (9, 3)  cost=55, cap=3
  W4: (5, 5)  cost=70, cap=5
  W5: (2, 6)  cost=40, cap=3

Customer positions:
  C0: (2, 7)
  C1: (4, 3)
  C2: (6, 8)
  C3: (8, 2)
  C4: (1, 4)
  C5: (5, 6)
  C6: (3, 9)
  C7: (7, 1)
  C8: (9, 7)
  C9: (4, 5)
m = dm.Model("warehouse_quadratic")

# Binary: open warehouse i?
open_w = m.binary("open", shape=(n_warehouses,))

# Continuous: fraction of customer j served by warehouse i
alloc = m.continuous("alloc", shape=(n_warehouses, n_customers), lb=0.0, ub=1.0)

# Objective: fixed costs + distance shipping + quadratic congestion.
# NOTE: `dist_sq[i, j] * alloc[i, j]` is LINEAR in the decision variable -- dist_sq
# is data. The congestion term `alloc[i, j] ** 2` is what makes this an MIQP.
gamma = 20.0  # congestion coefficient

fixed_term = dm.sum(lambda i: fixed_costs[i] * open_w[i], over=range(n_warehouses))
shipping_term = dm.sum(
    lambda i: dm.sum(lambda j: dist_sq[i, j] * alloc[i, j], over=range(n_customers)),
    over=range(n_warehouses),
)
congestion_term = gamma * dm.sum(
    lambda i: dm.sum(lambda j: alloc[i, j] * alloc[i, j], over=range(n_customers)),
    over=range(n_warehouses),
)
m.minimize(fixed_term + shipping_term + congestion_term)

# Each customer fully served
for j in range(n_customers):
    m.subject_to(dm.sum(lambda i: alloc[i, j], over=range(n_warehouses)) == 1.0, name=f"serve_{j}")

# Linking: only open warehouses can serve
for i in range(n_warehouses):
    for j in range(n_customers):
        m.subject_to(alloc[i, j] <= open_w[i], name=f"link_{i}_{j}")

# Capacity constraints
for i in range(n_warehouses):
    m.subject_to(
        dm.sum(lambda j: alloc[i, j], over=range(n_customers)) <= capacities[i] * open_w[i],
        name=f"capacity_{i}",
    )

# Budget: at most 3 warehouses
m.subject_to(dm.sum(lambda i: open_w[i], over=range(n_warehouses)) <= 3, name="budget")

# Verify the claim in the markdown above rather than asserting it.
from discopt._relax.problem_classifier import ProblemClass, classify_problem

assert classify_problem(m) == ProblemClass.MIQP, classify_problem(m)
print(f"Problem class with congestion term:    {classify_problem(m)}")

result = m.solve()

print(f"Status:     {result.status}")
print(f"Objective:  {result.objective:.2f}")
print(f"Gap:        {result.gap}")
print(f"Nodes:      {result.node_count}")
print(f"Time:       {result.wall_time:.3f}s")
OA: generating OA cuts for 0 of 77 rows (77 convex; the rest are either nonconvex or already exact in the master)
Problem class with congestion term: ProblemClass.MIQP
Status:     optimal
Objective:  366.60
Gap:        0.0
Nodes:      0
Time:       0.351s
# Display results
open_vals = result.value(open_w)
alloc_vals = result.value(alloc)

print("Warehouse decisions:")
for i in range(n_warehouses):
    status = "OPEN" if open_vals[i] > 0.5 else "closed"
    pos = warehouse_pos[i]
    print(f"  W{i} at ({pos[0]:.0f}, {pos[1]:.0f}): {status}")

print("\nCustomer assignments:")
for j in range(n_customers):
    assignments = []
    for i in range(n_warehouses):
        if alloc_vals[i, j] > 0.01:
            assignments.append(f"W{i} ({alloc_vals[i, j]:.0%})")
    pos = customer_pos[j]
    assigned = ", ".join(assignments)
    print(f"  C{j} at ({pos[0]:.0f}, {pos[1]:.0f}) -> {assigned}")
Warehouse decisions:
  W0 at (1, 8): closed
  W1 at (3, 2): closed
  W2 at (7, 9): closed
  W3 at (9, 3): OPEN
  W4 at (5, 5): OPEN
  W5 at (2, 6): OPEN

Customer assignments:
  C0 at (2, 7) -> W4 (41%), W5 (59%)
  C1 at (4, 3) -> W3 (11%), W4 (61%), W5 (28%)
  C2 at (6, 8) -> W3 (6%), W4 (66%), W5 (28%)
  C3 at (8, 2) -> W3 (70%), W4 (30%)
  C4 at (1, 4) -> W4 (41%), W5 (59%)
  C5 at (5, 6) -> W3 (4%), W4 (64%), W5 (32%)
  C6 at (3, 9) -> W4 (44%), W5 (56%)
  C7 at (7, 1) -> W3 (65%), W4 (35%)
  C8 at (9, 7) -> W3 (55%), W4 (45%)
  C9 at (4, 5) -> W4 (61%), W5 (39%)
4. QP Relaxation in Branch and Bound#
At each node of the B&B tree, the integrality constraints are dropped and the resulting QP relaxation is solved. For an MIQP with a convex quadratic objective (\(Q \succeq 0\)), each relaxation is a convex QP, which can be solved to global optimality in polynomial time.
The key insight is that the QP relaxation provides a lower bound on the optimal MIQP objective at that node. If the QP solution happens to be integer-feasible, the node is fathomed. Otherwise, the solver branches on a fractional integer variable, creating two child nodes.
discopt solves these relaxations with POUNCE, its pure-Rust port of the Ipopt primal-dual interior-point method [Wächter and Biegler, 2006]. The engine works on the algebraically extracted \(Q\), \(c\), \(A\), \(b\) rather than on a general NLP callback interface, and the point it returns is re-checked for primal feasibility and KKT stationarity before it is accepted — a point failing either check is refused rather than reported.
Why QP-specific solvers matter#
A general-purpose NLP solver could solve each QP relaxation, but a QP-specific IPM has key advantages:
Constant Hessian: \(Q\) does not change between iterations, so the Hessian callback is a constant and factorizations can be reused
Constant Jacobian: the constraints are linear, so the Jacobian is evaluated once rather than at every iterate
Warm-starting: the QP solution at a parent node provides a good initial point for child nodes
Finite convergence: QP IPMs converge in \(O(\sqrt{n})\) iterations with polynomial-time guarantees [Nocedal and Wright, 2006]
# Timing breakdown for the portfolio problem.
#
# The accounting model (discopt._timing): `rust_time` and `python_time` are
# measured at FFI boundaries and PARTITION the wall clock. `pounce_time` and
# `jax_time` are diagnostic SUBSETS -- pounce <= rust, jax <= python -- so they
# must not be subtracted from the wall as if they were separate buckets.
m_timing, _, _ = build_portfolio(K=5)
res_timing = m_timing.solve()

print("Solver timing breakdown:")
print(f"  Total wall time: {res_timing.wall_time:.4f}s")
print(f"  Rust time:       {res_timing.rust_time:.4f}s  (B&B tree, simplex, POUNCE)")
print(f"  Python time:     {res_timing.python_time:.4f}s  (modeling layer, relaxation build)")
print(f"    of which POUNCE: {res_timing.pounce_time:.4f}s  (subset of Rust time)")
print(f"    of which JAX:    {res_timing.jax_time:.4f}s  (subset of Python time)")
print(f"  rust + python = {res_timing.rust_time + res_timing.python_time:.4f}s")
print()
print(f"  B&B nodes:       {res_timing.node_count}")
if res_timing.node_count > 0:
    print(f"  Time per node:   {res_timing.wall_time / res_timing.node_count * 1000:.2f}ms")
print()
print("JAX time is 0.0: JAX is not on discopt's default solve path.")
Solver timing breakdown:
  Total wall time: 0.0654s
  Rust time:       0.0037s  (B&B tree, simplex, POUNCE)
  Python time:     0.0617s  (modeling layer, relaxation build)
    of which POUNCE: 0.0037s  (subset of Rust time)
    of which JAX:    0.0000s  (subset of Python time)
  rust + python = 0.0654s

  B&B nodes:       73
  Time per node:   0.90ms

JAX time is 0.0: JAX is not on discopt's default solve path.
5. Exercise: Lot-Sizing with Quadratic Holding Costs#
A manufacturing plant must plan production over \(T = 8\) periods to meet known demand \(d_t\). In each period, the plant can decide to set up production (incurring a fixed cost) and produce some quantity. Inventory is carried between periods, and holding costs are quadratic (reflecting deterioration, warehouse congestion, or opportunity cost that grows with inventory level).
subject to:
\(I_t = I_{t-1} + x_t - d_t \quad \forall t\) (inventory balance)
\(x_t \leq M \cdot z_t \quad \forall t\) (setup linking)
\(I_0 = 0\), \(I_T = 0\) (no initial/final inventory)
\(z_t \in \{0, 1\}\), \(x_t \geq 0\), \(I_t \geq 0\)
The quadratic term \(h \cdot I_t^2\) makes this an MIQP. The binary variables \(z_t\) represent the fixed-cost setup decision.
Your task: Complete the model below.
# Problem data
T = 8
demand = np.array([20, 30, 25, 35, 15, 40, 20, 25])
setup_cost = 100.0  # fixed cost per setup
prod_cost = 2.0  # per-unit production cost
hold_cost = 0.5  # quadratic holding cost coefficient
M_prod = float(demand.sum())  # big-M for production capacity

print(f"Periods: {T}")
print(f"Demand:  {demand}")
print(f"Total demand: {demand.sum()}")
print(f"Setup cost: {setup_cost}, Production cost: {prod_cost}/unit")
print(f"Holding cost: {hold_cost} * I^2")

# --- YOUR CODE HERE ---
# m = dm.Model("lot_sizing")
# z = m.binary("setup", shape=(T,))              # setup in period t?
# x = m.continuous("produce", shape=(T,), lb=0)   # production quantity
# I = m.continuous("inventory", shape=(T,), lb=0)  # end-of-period inventory
#
# # Objective: setup + production + quadratic holding
# m.minimize(
#     dm.sum(lambda t: setup_cost * z[t] + prod_cost * x[t] + hold_cost * I[t] * I[t],
#            over=range(T))
# )
#
# # Inventory balance: I[t] = I[t-1] + x[t] - d[t]
# m.subject_to(I[0] == x[0] - demand[0], name="inv_balance_0")  # I_{-1} = 0
# for t in range(1, T):
#     m.subject_to(I[t] == I[t - 1] + x[t] - demand[t], name=f"inv_balance_{t}")
#
# # Final inventory = 0
# m.subject_to(I[T - 1] == 0, name="final_inv")
#
# # Setup linking
# for t in range(T):
#     m.subject_to(x[t] <= M_prod * z[t], name=f"setup_link_{t}")
#
# result = m.solve()
# print(f"Objective: {result.objective:.2f}")
Periods: 8
Demand:  [20 30 25 35 15 40 20 25]
Total demand: 210
Setup cost: 100.0, Production cost: 2.0/unit
Holding cost: 0.5 * I^2
# --- Solution ---
m = dm.Model("lot_sizing")
z = m.binary("setup", shape=(T,))
x = m.continuous("produce", shape=(T,), lb=0.0, ub=M_prod)
inv = m.continuous("inventory", shape=(T,), lb=0.0, ub=M_prod)

# Objective: fixed setup + linear production + quadratic holding
m.minimize(
    dm.sum(
        lambda t: setup_cost * z[t] + prod_cost * x[t] + hold_cost * inv[t] * inv[t],
        over=range(T),
    )
)

# Inventory balance: inv[t] = inv[t-1] + x[t] - d[t], with inv[-1] = 0
m.subject_to(inv[0] == x[0] - demand[0], name="inv_balance_0")
for t in range(1, T):
    m.subject_to(inv[t] == inv[t - 1] + x[t] - demand[t], name=f"inv_balance_{t}")

# Final inventory = 0
m.subject_to(inv[T - 1] == 0, name="final_inv")

# Setup linking: can only produce if setup
for t in range(T):
    m.subject_to(x[t] <= M_prod * z[t], name=f"setup_link_{t}")

result = m.solve()

print(f"Status:     {result.status}")
print(f"Objective:  {result.objective:.2f}")
print(f"Gap:        {result.gap}")
print(f"Nodes:      {result.node_count}")
print(f"Time:       {result.wall_time:.3f}s")

# Display production plan
setup_vals = result.value(z)
prod_vals = result.value(x)
inv_vals = result.value(inv)

print(
    f"\n{'Period':>6} {'Demand':>8} {'Setup?':>7}"
    f" {'Produce':>9} {'Inventory':>10} {'Hold Cost':>10}"
)
print("-" * 55)
for t in range(T):
    setup_flag = "Yes" if setup_vals[t] > 0.5 else "No"
    hc = hold_cost * inv_vals[t] ** 2
    print(
        f"{t + 1:6d} {demand[t]:8d} {setup_flag:>7}"
        f" {prod_vals[t]:9.1f} {inv_vals[t]:10.1f} {hc:10.2f}"
    )
OA: generating OA cuts for 0 of 17 rows (17 convex; the rest are either nonconvex or already exact in the master)
Status:     optimal
Objective:  1220.00
Gap:        2.031108539587835e-09
Nodes:      0
Time:       0.159s

Period   Demand  Setup?   Produce  Inventory  Hold Cost
-------------------------------------------------------
     1       20     Yes      20.0        0.0       0.00
     2       30     Yes      30.0        0.0       0.00
     3       25     Yes      25.0        0.0       0.00
     4       35     Yes      35.0        0.0       0.00
     5       15     Yes      15.0        0.0       0.00
     6       40     Yes      40.0        0.0       0.00
     7       20     Yes      20.0        0.0       0.00
     8       25     Yes      25.0       -0.0       0.00
6. Summary#
In this tutorial we covered:
Topic |
Key takeaway |
|---|---|
MIQP definition |
QP + integrality constraints; solved via B&B with QP relaxations |
Portfolio optimization |
Cardinality constraints turn Markowitz into MIQP; diminishing returns of diversification |
Warehouse selection |
Quadratic congestion costs + binary open/close decisions; squared data (\(d_{ij}^2\)) does not raise the problem class, squared variables do |
QP relaxation in B&B |
Convex QP at each node provides lower bound; specialized IPM solves efficiently |
Lot sizing |
Quadratic holding costs + fixed setup costs = classic MIQP |
When does MIQP arise?#
Look for problems that combine:
Quadratic costs or objectives: variance, squared error, quadratic penalties, interaction terms
Discrete decisions: select/reject, open/close, setup/no-setup, assign to groups
If the quadratic terms involve only continuous variables and \(Q \succeq 0\), the QP relaxation at each B&B node is convex, making the MIQP tractable for moderate sizes. If \(Q\) is indefinite, the problem becomes much harder (non-convex MIQP).
Next steps#
MINLP tutorial: When constraints or objectives are nonlinear beyond quadratic, see
notebooks/minlp_examples.ipynbAdvanced features: Cutting planes and learned relaxations in
notebooks/advanced_features.ipynbDifferentiable optimization: Using gradients through the solver for end-to-end learning in
notebooks/decision_focused_learning.ipynb
References#
[Markowitz, 1952] — Portfolio selection and mean-variance optimization
[Wolsey, 1998] — Integer Programming (textbook)
[Boyd and Vandenberghe, 2004] — Convex Optimization (QP theory and interior-point methods)
[Land and Doig, 1960] — Branch and Bound algorithm
[Nocedal and Wright, 2006] — Numerical Optimization (IPM details)